Tuesday, July 31, 2012

Friday, September 11, 2009

Monday, May 4, 2009
OpenID's hidden value in Application Integration
I haven't seen any articles discussing this subject - but let me know if you know of any and i'll link.
OpenID is a hugely valuable standard protocol for federated authentication and by the looks of things adoption is and will coninue to grow at a phenomenal rate.
The advantage of OpenID over traditional authentication systems is well known - it saves you having to remember multiple usernames and passwords. An additional advantage of OpenID over other Internet authentication systems is that it is completely decentralized and anyone can create their own authentication provider.
Consider an enterprise that has some internal applications that can't be seen by the web itself. That enterprise can set up an OpenID provider to let all their staff log into these internal applications. Additionally however they can allow that provider to be seen from the outside world and so allow staff to log onto applications on the web using that same OpenID.
Cool! However there is an additional benefit when integrating applications which isn't quite as explicit and you really only notice at development stage. In particular this is very important for creators of 3rd party software. That is:
If a 3rd party application supports OpenID then no matter the language or platform it can be easily integrated into an existing software site or portal.
What do i mean by this? Well recently I created a web site that used a 3rd party open source system that had traditional basic authentication as well as OpenID. Great. However later on i wanted to add a nice blogging feature using another 3rd party ... but the problem was they didn't support OpenID.
Now, let's ignore all the technical detail here such as Single Sign On between applications - sure this is cool but i'd be willing to bet that even if the user had to log in using their OpenID twice into these two applications it is miles ahead of the common current issue where you suddenly need to remember a username and password again (and all the management that goes with that). Consider the case where most of us may integrate 4 or 5 separate systems to create a solution and suddenly the fact that ONE of then uses OpenID but the other 4 require old style username/password authentication really isn't much of a benefit.
In my case i chose not to go for them. I simply didn't have time to write OpenID support for their products. I was quite happy for the applications to run independently on the server with a simple link bewteen each ... even if they had to log in to each - so long as i didn't have to manage duplicate accounts. The great thing though is that the managament of their login details etc could all be done centrally. I know from my experience supporting OpenID.ORG that the time taken to support users dwarfs almost everything else you do.
So although it may sound obvoius that an OpenID account can really help you log into multiple applications with the same details, it's not until you start pulling together 3rd party applications you realize how valuable this is even on a single website or portal.
Going back to our enterprise - they can now create a cool portal that integrates custom software, 3rd party products & remote services, without worrying about user managament. And i know from current personal experience how big a win that will be.
Tuesday, April 14, 2009
xUnit & TeamCity
Having used nUnit for some time and Visual Team System's test architecture i was recently interested in putting this to work on my own project as part of an automated build & test architecture. The test architecture of Visual Team system isn't particualy suited to Continuous Integration as you need to reference assemblies that only seem to be part of Visual Studio and you're not allowed to distribute these. I considered nUnit as this is what i am used to but as it's my own projected decided to give xUnit a shot as it seems to be the next logical step in good testing practices.
I had started using ThoughtWords CI server but after banging my head on the table a few times in my failed attempts to integrate xUnit, and on the advice of Brad Wilson, decided to look at TeamCity.
With some help from Brad I managed to get this working but as it was still a little tricky (i only rarely change this infrastruture of this kind of thing once it it set up) i decided to document how to do it. Note that you can't just point TeamCity at the .sln file in this case because you need to TELL it that it must run your xUnit tests and clearly the .sln file doesn't know about them. So what you need to do is create an MSBuild file where you can tell TeamCity to (a) build your solution file AND (b) run your tests via xUnit.
1. Download and Insteall team city. Configure this to get it building your base code ( i won't document this as there are loads of places to find out more).
2. Go to the folder where your .sln file sites and create a file called "mysolution.msbuild" (or something similar).
3. Enter the following Xml:
<project defaulttargets="Build" xmlns="http://schemas.microsoft.com/developer/msbuild/2003">
<usingtask assemblyfile="[RelativePathToXUnit]xunit.runner.msbuild.dll" taskname="Xunit.Runner.MSBuild.xunit">
<target name="Build">
<msbuild projects="mysolution.sln" targets="Build" properties="Configuration=Debug">
<xunit assembly="[RelativePathToProject]bin\Debug\MyProjectTests.dll">
</xunit></msbuild></target>
</usingtask></project>
* Remember to replace [RelativePathToXUnit] with the relative path from your solution file to where the xunit runner assembly can be found. Also make sure [RelativePathToProject] is changed to point to the project where your tests can be found.
4. Now via the TeamCity GUI in the "Build Runner" tab of your project, select MSBuild and add the relative path to your "mysolution.msbuild" file relative to your checkout directory (in my case it is often "/mysolution.msbuild").
5. Now you can run your build and you'll find all your unit tests are run.
Tuesday, January 13, 2009
Microsoft Tags, QR Codes and OpenID
I have used Barcodes and QR Codes in the past on some projects and played around a bit. Well, this morning i saw Microsoft released "Microsoft Tags" as a beta at CES 2009.
Clearly from my own selfish perspective, what i'd like to see if OpenID (disclaimer, i run http://OpenID.ORG) go OPEN in the real world. So, at a conference you could put a QR Code or Microsoft tag on your badge, t-shirt, hat or what ever. Maybe on the back of a card, on your company documentation, promotional material and so on.
If your OpenID is encoded in there then people could save you as a contact direct from your t-shirt :)
Thoughts? Other ideas?
Here is my OpenID (http://weblivz.openid.org) as a Microsoft tag (which would be printed out of course):

... and here is my OpenID as a QR Code :

Update : Sure enough, i installed the Tag reader on my PDA and simply pointed the phone at the image and it took me to my OpenID page in the web browser. Very nice!
They say more formats may be supported in the future - hope they add QR Codes to that list!
Tuesday, January 6, 2009
Twitter phishing issues
I agree with this article in the main, but there are some things worth pointing out… baring mind the majority and most concerning of these phishing issues came from people giving their credentials out and the 3rd parties assuming their identities and the associated trust with that.
1. oAuth could have allowed me to provide access for 3rd party systems in a case by case basis - not providing the credentials that could be stored and re-used.
2. oAuth would allow me to disable access immediately for a 3rd party site.
3. oAuth, as used in GMail, could be used to restrict the levels of access you permit of 3rd party applications. Therefore i may allow a site to read my contacts (which most do) but not sent replies or DM’s on my behalf (in fact this is what GMail can allow).
... I totally get that anyone can @ you on twitter - but i would be unlikely to click a random link. It it came from a friend - especially DM I am MUCH more likely to click it.
Only question i have is why did the phishing sites not use tinyURL or something to mask the link?
Saturday, January 3, 2009
In the zone
Every New Year we promise to change something about ourselves. Well, this year i'm THINKING of trying something new (for me). Starting Monday 5th Jan, I am going to change timezone.... well, for an experimental period anyway! I was inspired to try this by reading this article by @4entrepreneur ... and the fact that it's harder to work at home during the day when my daughter is around (not yet at nursery).
What does that mean? Well, for 2 weeks (gotta trial this and start somewhere!) i am going to work to PST time. So that means i will be working through the night, at the same time as most of the tech activity on Twitter. It also means i can see whether coding in the evenings really is more beneficial. I used to write all my code books into the early hours but when i had the kids things reversed and i starting getting up very early.
I will blog and tweet as i go.
But i need to get a few typical daily timetables from tech folk working in PST (when do you rise, work, go to sleep and so on?). If anyone can comment, email or DM on twitter it would be much appreciated!! I could easily subtract 8 from my normal day, but want something real.
Anyone NOT in PST already work to that timezone, perhaps out of necessity via remote working?
Monday, December 29, 2008
The Social Netbook
It is perhaps reasonably well known that i won a Netbook courtesy of Vodafone last month. As soon as i got it I started to think about how it could make its way into the everyday lives of the people i know. So, here are a couple of suggestions:
Social Software
The first thing is that these Netboos need to come pre-bundled with social software. Most people won't buy a Netbook to write code or even compile documents. Most will buy them to "get on the web" as Netbooks are a great opportunity to point them at things to do.
I imagine a wizard in startup that suggests the services you may like to use, takes you through a signing up process and installs and configures the appropriate software for you.
An example is ...
We're talking about a lightweight laptop that has limited disk space and less than the typical laptop in terms of memory and processor speeds. It is pretty much reliant on you being online. So why not use the cloud??
An example ...
Social Software
The first thing is that these Netboos need to come pre-bundled with social software. Most people won't buy a Netbook to write code or even compile documents. Most will buy them to "get on the web" as Netbooks are a great opportunity to point them at things to do.
I imagine a wizard in startup that suggests the services you may like to use, takes you through a signing up process and installs and configures the appropriate software for you.
An example is ...
- Configure an OpenID account
- Create Twitter account (they should be doing (1) by now!) and install software
- Create a flickr and twitpic account and configure appropriately.
- Set up friendfeed.
- Create a MySpace/Facebook account and store shortcuts.
- Install UStream/Qik and configure an account.
- Email account.
- blah dee blah ...
(Other suggestions ??)
Cloud ServicesWe're talking about a lightweight laptop that has limited disk space and less than the typical laptop in terms of memory and processor speeds. It is pretty much reliant on you being online. So why not use the cloud??
An example ...
- An Amazon/Mesh storage account direct from your desktop ... via your OpenID account ;)
- Allow direct storage and management of pictures, video and so on on the clound (maybe on top of (1)).
- Perhaps even EC2 could be somehow synchd with Netbooks to allow complex calculations to be carried out on the cloud. Idea here?
In short there is potentially a huge opportunity for services to get on board this new wave of laptop and whilst rolling out an empty laptop works fine for me, there are many others who could climb on board the social wagon if they were given some help along the way!
Who else uses a Netbook? What do you think?
Sunday, December 7, 2008
Xtranormal - create your own 3D animation
Keeping the kids amuzed on a Sunday morning can be somewhat slow, but when @joecar mentioned Xtranormal to us this morning we tried it out... and how addictive it has become. To me, sure - but my 5 yr old loves it.
So we created a story (i helped him out but all the ideas, script, names and so on were his and you can perhaps guess someof his influences!).
Here is it below - you can also see it here and in youtube . I suggest you try it out - some things still to be worked on, but in general very, very well done.
Wednesday, December 3, 2008
Secret Santa on Twitter
This Christmas i'm running a secret santa on Twitter.
The idea is that - you contact me with your twitter name and you will be added to the list - this will stop on Friday December 12 (I'll extend to December 19 if need be).
You will then be contacted with the twitter username of the person you are to get a "gift" for. The gift can be a cool URL, a connection with someone, a beta invite - anything useful (probably best avoid sending anything involving advertising).
When done (i.e. after i have contacted a secret link), you simply send the following:
@username #secretsanta [message]
The #secretsanta is just so we can follow this happening (and the person knows why you are contacting them).
If wished, i could publish the list after Christmas.
Update - Who's involved?
@weblivz
@katiebarrowman
@jenjeng
@KyleMacRae
@holeinhiseye
@salidatious
@garymurning
@peewii
@frontofficebox
@jimwolffman
Tuesday, November 18, 2008
A winner with Vodafone Live Guy
Today i spent more than a few hours hunting for @vodafoneliveguy - you can see my twitter feed on the day at http://twitter.com/weblivz. This is a treasure hunt style contest where you need to find the vodafone live guy who is constantly moving throughout the city. It is a really nice idea, something i read about a while back in SmartMobs. You need to follow his updates via GPS, blog, twitter and more and try and guess where he is.
It was more than just winning the laptop i was interested in. I wanted to participate in something like this - as well as livestream it as much as possible, armed with a PDA, a laptop with some web access and my feet (i wasn't in a car, nor considered paying for taxi's to travel around).
The Morning
At 9.10 AM after dropping my son off at school, i got the train into Glasgow and the game started. I was pretty determined to find him - but i wanted to see how i would use technology to do so.
I went to Queens Street and immediately headed to Bothwell Street tracing the path from the old Herald offices opposite Livingstone Tower at Strathclyde Univeristy. I went to Bothwell Street and after looking around, figured he had went into the centre of town. So then i checked into Borders to fire up the laptop and check his map.... it said he was in Bothwell Street, but much further up. So back i headed and outside central approached a rather worried looking chap dressed in red and put my hand out to shake it. Perhaps he was a tourist thinking were were always thing friendly, but nevertheless he just kind of looked at me as I realized this was not my man. I felt pretty stupid, but onwards i went.
I was then at Bothwell Street and despite me being roughly where he was for about 15 minutes before anyone else turned up (i could tell the instant a challenger arrived, just outside Weatherspoons on Bothwell Street) and despite the picture of the car park, i just couldn't locate him.
I tried to think of where he could head... the Clyde was my thought - a fairly major part of Glasgow. So i walked down that way, only to discover he had been found. Fek... and i think it was the guy who ran past me who found him (i'd love to hear that story too!).
I was beaten but not out and the day was young. I recorded a video on my mobile where i talk about the fact he started at Colville Building of Strathclyde University (which is where the Headquarters are in detective series Taggart) and how he was at the Livingstone Tower, named after David Livingstone.

The Afternoon
As i sat in St Enoch (suggested by my wife), i read that he was at the Sas Raddison and spent 15 mins there before realizing i was never going to find him. I then read he had to moved into MY backyard - the West End! On the underground to Hillhead - guessing he would go to Glasgow University and the Hunterian Museum, only to find he was going to Kelvingrove.
So i walked pretty quickly to the museum and figured i'd go in the back way and surprise him. But as i went round the corner, what do i see? A big red jacket and a bunch of people around him. I approached to congratulate the winner(s) only to find none of them knew the phrase. I immediately said "You're the LiveGuy and I'm a Vodafone Winner" and sure enough, the prize was mine.
It turns out Jon Sykes, a lecturer at Glasgow Caladonian University had taxied two lots of students to Kelvingrove, but none of them knew the crucial phrase. So i was either lucky, or had studied harder! Put it this way, it wasn't exactly Maradona handball in the box - more like that second goal ;)

I had a nice chat with liveguy and friend for a while telling them of my day and the close misses and they went their way and i went mine. I recorded a video just after i had spoken with them.

I then went into the BeanScene cafe opposite the Galleries and relaxed for an hour or so, checked from mail, read some papers.
There's More
I do some work for Conscia and sometimes use their desks. Now, yesterday i had told them of the game and figured they had just ignored me - especially as i had heard nothing from any of them all day. Well, turns out they had been keeping tabs on the live guy.
I walked into the office and said "Yes, I won" only to be told, "Yes, so did Chris". Now, i assumed this to be a wind up, but it turns out that @vodafoneliveguy had left his GPS on and he made his way into town and stopped around the corner from the offices. About 10 of them apparently ran out in various directions and the first guy (Mark) didn't know the phrase either - "Can I have the laptop please" is apparently what he said. In fact the one that did (Chris) had made a call back to someone else (Dominic) in the office who told him what it was.
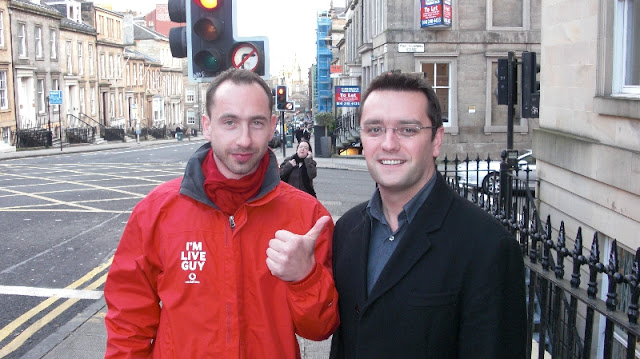
To end it, one of the guys (Jim) had went to the bank which is nearby where this all happened and came out only to see much of this going on. He had been there the whole time and despite HIM being the one i initially told AND HIM being the one that reminded everyone else this morning after i had told them yesterday, he had temporarily let his guard down. Otherwise he would be a happy owner of a new laptop.
Update: Apparently Mark had an iPhone with GPS tracking on it and could literally watch them drive into town, stop and emerge from the offices they had been in - with lots of people following him as they knew this! The only problem was he didn't know the winning phrase and Chris jumped in (ouch!).
What a mad day. Feet are sore, but happy that i won a laptop and even happier that i was part of all this, especially as by the time it hits London he's need to wear a disguise.
So i guess the moral to all of this is that social networking works - but only when you know a bit about the detail. Deeplinking is cool even in a social sense so long as you read what's at the end of that link.
It was more than just winning the laptop i was interested in. I wanted to participate in something like this - as well as livestream it as much as possible, armed with a PDA, a laptop with some web access and my feet (i wasn't in a car, nor considered paying for taxi's to travel around).
The Morning
At 9.10 AM after dropping my son off at school, i got the train into Glasgow and the game started. I was pretty determined to find him - but i wanted to see how i would use technology to do so.
I went to Queens Street and immediately headed to Bothwell Street tracing the path from the old Herald offices opposite Livingstone Tower at Strathclyde Univeristy. I went to Bothwell Street and after looking around, figured he had went into the centre of town. So then i checked into Borders to fire up the laptop and check his map.... it said he was in Bothwell Street, but much further up. So back i headed and outside central approached a rather worried looking chap dressed in red and put my hand out to shake it. Perhaps he was a tourist thinking were were always thing friendly, but nevertheless he just kind of looked at me as I realized this was not my man. I felt pretty stupid, but onwards i went.

I was then at Bothwell Street and despite me being roughly where he was for about 15 minutes before anyone else turned up (i could tell the instant a challenger arrived, just outside Weatherspoons on Bothwell Street) and despite the picture of the car park, i just couldn't locate him.

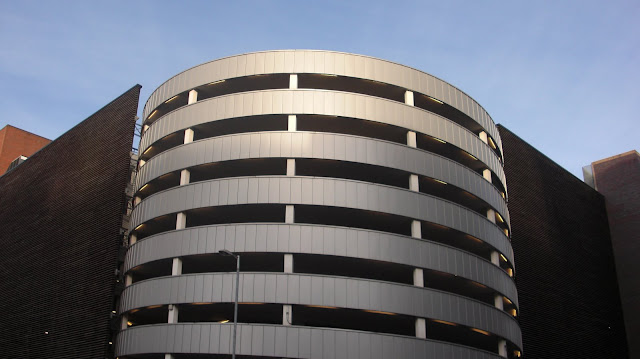
I tried to think of where he could head... the Clyde was my thought - a fairly major part of Glasgow. So i walked down that way, only to discover he had been found. Fek... and i think it was the guy who ran past me who found him (i'd love to hear that story too!).

I was beaten but not out and the day was young. I recorded a video on my mobile where i talk about the fact he started at Colville Building of Strathclyde University (which is where the Headquarters are in detective series Taggart) and how he was at the Livingstone Tower, named after David Livingstone.

The Afternoon
As i sat in St Enoch (suggested by my wife), i read that he was at the Sas Raddison and spent 15 mins there before realizing i was never going to find him. I then read he had to moved into MY backyard - the West End! On the underground to Hillhead - guessing he would go to Glasgow University and the Hunterian Museum, only to find he was going to Kelvingrove.



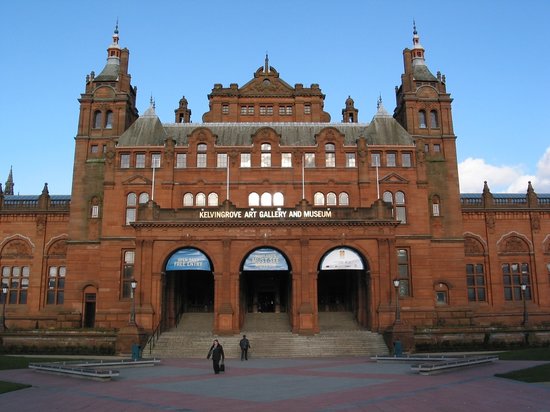
So i walked pretty quickly to the museum and figured i'd go in the back way and surprise him. But as i went round the corner, what do i see? A big red jacket and a bunch of people around him. I approached to congratulate the winner(s) only to find none of them knew the phrase. I immediately said "You're the LiveGuy and I'm a Vodafone Winner" and sure enough, the prize was mine.
It turns out Jon Sykes, a lecturer at Glasgow Caladonian University had taxied two lots of students to Kelvingrove, but none of them knew the crucial phrase. So i was either lucky, or had studied harder! Put it this way, it wasn't exactly Maradona handball in the box - more like that second goal ;)


I had a nice chat with liveguy and friend for a while telling them of my day and the close misses and they went their way and i went mine. I recorded a video just after i had spoken with them.
I then went into the BeanScene cafe opposite the Galleries and relaxed for an hour or so, checked from mail, read some papers.
There's More
I do some work for Conscia and sometimes use their desks. Now, yesterday i had told them of the game and figured they had just ignored me - especially as i had heard nothing from any of them all day. Well, turns out they had been keeping tabs on the live guy.
I walked into the office and said "Yes, I won" only to be told, "Yes, so did Chris". Now, i assumed this to be a wind up, but it turns out that @vodafoneliveguy had left his GPS on and he made his way into town and stopped around the corner from the offices. About 10 of them apparently ran out in various directions and the first guy (Mark) didn't know the phrase either - "Can I have the laptop please" is apparently what he said. In fact the one that did (Chris) had made a call back to someone else (Dominic) in the office who told him what it was.
To end it, one of the guys (Jim) had went to the bank which is nearby where this all happened and came out only to see much of this going on. He had been there the whole time and despite HIM being the one i initially told AND HIM being the one that reminded everyone else this morning after i had told them yesterday, he had temporarily let his guard down. Otherwise he would be a happy owner of a new laptop.
Update: Apparently Mark had an iPhone with GPS tracking on it and could literally watch them drive into town, stop and emerge from the offices they had been in - with lots of people following him as they knew this! The only problem was he didn't know the winning phrase and Chris jumped in (ouch!).
What a mad day. Feet are sore, but happy that i won a laptop and even happier that i was part of all this, especially as by the time it hits London he's need to wear a disguise.
So i guess the moral to all of this is that social networking works - but only when you know a bit about the detail. Deeplinking is cool even in a social sense so long as you read what's at the end of that link.
Wednesday, November 5, 2008
OpenID "Friend" based Attributes
Something i have been thinking about in line with some recent discussion on the OpenID mailing lists has been techniques to verify someone's identity and the attributes that are associated with it.
My initial thoughts comes up with the following:
Reputation
In this case, the longer you use your OpenID, the more people will come to know it is associated with you. I’d be interested in how we could explicitly extend this concept to support a distributed reputation system where you can attach OpenID Reputation points which are assigned from other sites. These could even be broken down into types of reputation. The longer and more you use it the more reputation points. Even sending an email that isn’t spam etc via Gmail or Windows Live could “increment” your reputation score (like pagerank, but for OpenID).
Friend Verification
Slightly more explicit and extension of the above whereby friends can verify things you write down about yourself so that others can trust them more. John says he works at Google Inc and Brian has verified this etc.
Central Validation
Shibboleth model and probably needed for institutions who perhaps verify things such as “Yes, this is definitely Dr. Livingstone” etc.
More thinking
However, i can't think of a reason why OpenID AX couldn't support attributes from third parties that are signed and stored with the OpenID. This way an institution could be given a users OpenID, make statements about them and return the signed statements/attributes which can then be stored anywhere with that users OpenID profile.
Someone who wants to get those attributes can easily check via the insituions publically available key that thse attributes have not been altered in any way.
Extending this you could have a plethora of OpenID attribute information that is both unverified and strongly verified.
Saturday, November 1, 2008
OpenSearch and JSON
In the limited spare time that i seem to have these days, one of the things i've been looking at is OpenSearch, "... a collection of simple formats for the sharing of search results".
OpenSearch is slowing gaining lots of traction and each of the major browsers now allow you to add an OpenSearch to your toolbar automatically (although the User Experience certainly needs work!).
In my current consultancy work for the NHS I was asked to extend the search API I wrote some months back which works against FAST, and enable any third party site to ended some script in their site and make Ajax style queries. Last week I wrote this functionality (which returns custom Xml and Json) and sure enough it works great.
However, I like open stuff because it makes it easy for others to pick up and run and so after I added OpenSearch support via the usual description file and tested this with Internet Explorer et al and it worked, i decided to look at whether i could use OpenSearch as the actual syndication format.
Now, if this all ran on the same domain there would be no problem in pulling back Atom or RSS and formatting it for display. But in a cross domain architecture you can't do this due to Same Origin Policy. So, using JSON-P we can enable OpenSearch queries over the wire.
To do that however, we need to have an OpenSearch format for JSON - in my case i simply took the Atom format as a starting point and mapped much of that and added in the OpenSearch elements and attributes.
So now you can take a few lines of code, add it to any page in the world and make an OpenSearch query using the template Uri and get an OpenSearch response which can be parsed and dislayed.
Early days but if it's useful to no-one else on the planet, it is useful to me :)
If interested, please try it out here. It queries over 100 million records so you will get results no matter what you type in, but the formats and data mappings are still being worked out.
PS. Would be *very* nice if we could query the OpenSearch discovery endpoint and ask for JSON to be returned. That way we could dynamically build all of the front end stuff that i can't do with the existing reponse (it returns an OpenSearch specific content type which is not trusted by browsers).
Saturday, October 11, 2008
Grassroots rail support
I've travelled on trains, planes and automobiles for so many years now and one thing that has yet to be resolved is telling you what is happening as it is happening. You are often left to try and guess what the problem is, or when the train will arrive - and this is worse at night when there's often no-one around to ask. Well, for years I always intended to build a grassroots support network for transport as the profilferation of mobile devices enabled more people to become involved using SMS and mobile browsing.
Well, below is a rough sketch (it's not too detailed as my son is pushing me to watch an Indiana Jones puppet show he has created, but you'll get the idea).

Friday, October 10, 2008
Thoughts on the Cloud API
I have seen quite a few diagrams on cloud computing but not something like the one below - (please tell me if you know of more and i'll update!).

You see what many leave out is that if you build your service on a third party service in the cloud and it closes down, you're screwed. Well, currently you are. You need to find a new provider, swap your data, change the api, modify your internal code. Which in simple terms, means your're screwed.
Now, it's not such a big deal if Amazon is your service (although this should still be a consideration) but if the POINT of all this open web stuff and open source and api's etc etc is to allow the little guy to provide services, then it IT a big deal. The little guy will just NOT get the trust for many businesses and it is a shame. Once their ideas are bought by a bigger company then they get exposure. But surely this is a shitty way to do things. Why not let the little guy in?
A good way for this to happen would be for the "cloud" (and in Scotland we have cloud computing every day of the year, with torrential rain computing thrown in) to support common (i hate saying standard!) API's. oAuth is arguably the most successful example of that to date (with PoCo to come), but OpenID is also another good example (oAuth is not used seamlessly by many a big company).
But surely we need to look at common API's for all services - or at least the service providers do. I want to use provider A today and provider B tomorrow. It should be a configuration change for the client (and a "swap provider" checkbox ;) ).
Internally however there should be a service provider data exchange API that allows swapping of data (and arguably hot swapping for back up - imagine service A and service B backing each other's data up whilst providing the same service!?). So when i ask to move, i can have all my data moved to the new provider (for a fee of course). Here's that API :
OK, so it's a little more complex than that, high level is a good place to start. I also like the idea of a higher level cloud API that provides common services for all kinds of cloud services. I know there has been lots of work on various SOAP style services at W3 and so on (transations, instrumentation etc) - not sure how this thinking all fits in with the cloud stuff but would love to hear/read about it.

You see what many leave out is that if you build your service on a third party service in the cloud and it closes down, you're screwed. Well, currently you are. You need to find a new provider, swap your data, change the api, modify your internal code. Which in simple terms, means your're screwed.
Now, it's not such a big deal if Amazon is your service (although this should still be a consideration) but if the POINT of all this open web stuff and open source and api's etc etc is to allow the little guy to provide services, then it IT a big deal. The little guy will just NOT get the trust for many businesses and it is a shame. Once their ideas are bought by a bigger company then they get exposure. But surely this is a shitty way to do things. Why not let the little guy in?
A good way for this to happen would be for the "cloud" (and in Scotland we have cloud computing every day of the year, with torrential rain computing thrown in) to support common (i hate saying standard!) API's. oAuth is arguably the most successful example of that to date (with PoCo to come), but OpenID is also another good example (oAuth is not used seamlessly by many a big company).
But surely we need to look at common API's for all services - or at least the service providers do. I want to use provider A today and provider B tomorrow. It should be a configuration change for the client (and a "swap provider" checkbox ;) ).
Internally however there should be a service provider data exchange API that allows swapping of data (and arguably hot swapping for back up - imagine service A and service B backing each other's data up whilst providing the same service!?). So when i ask to move, i can have all my data moved to the new provider (for a fee of course). Here's that API :
data.Transfer(newProviderURI);
OK, so it's a little more complex than that, high level is a good place to start. I also like the idea of a higher level cloud API that provides common services for all kinds of cloud services. I know there has been lots of work on various SOAP style services at W3 and so on (transations, instrumentation etc) - not sure how this thinking all fits in with the cloud stuff but would love to hear/read about it.
One Web, Many Cultures - Reaching Out
I'm not entirely sure where this post is going, nor do i have any conclusions in mind. I have simpy been thinking about this for some years and feel like writing it down. I'm not sure what tone it will have for the person reading, but it is intended to ask some questions rather than make any kind of statement! Let me first say that i am from Scotland and have live in England, Italy, Canada and Chile in the last 15 years - i wrote books and used the web constantly in each.
I listened to Kevin Marks interview with Jemima Kiss at the Guardian and other than Kevin sounding incredibly similar to a friend of mind, the part that jumped out of me was his comments that many of the big social networks have done well out of users they just didn't expect. US technology companies growing "execpectedly" from string user bases in Russia, Brazil, China and so on - in other words from users NOT in North America.
So, I wrote on Twitter :
Kevin Marks of Google made the point to me on Twitter that :
My wording wasn't great (140 characters isn't much!) so this is what i meant....
Much of the technology driving the web is coming from specific locations in the US - mostly California - there is some input from the rest of us through discussion groups and so on, but primarily it is driven offline. This is understandable on many points due to the huge concentration of top people over there who are much like myself - driven and excited by the potential of the web as a platform that can fit into the daily life of everyone on the planet - in the many different ways people will use it. Also, at the moment virtual working groups are still a work in progress.
Now, oftentimes i get frustrated that i'm not amongst it - i had hoped to some years back startig with OpenID - (every week on twitter there is another cool event somewhere in the US where all the guys and gals get together to push these things forward). However, something that must be more frustrating is little involvement other cultures in the rest of the world must feel - at least i speak (bad) English and can follow in the forums and blog posts (and every so often post in the forums). What if you speak Chinese and want to use oAuth? Or Spanish? Say you want to add to it or suggest a change? There are a few involved, but this is very much the exception and if you check the board membership for most of these initiatives you can see they are based in the US and often (but not always) part U.S. web companies.
I think it is a problem waiting for a solution - the problem is how to integrate other languages and cultures so that the open web can be something that fits for everyone. If Orkut surprisingly managed to get a dominant user base in Brazil, was there something different to what other social networks were offering which made this happen? Does anyone know? In Africa it is suggested the uptake of mobile phones will continue to be huge - how do these efforts fit into their plans for a social web?
There are many of these folks who do a lot of evangelizing for these efforts so perhaps they can get to know active people who could get involved in the core specifications from Europe, Asia, Africa, South America and so on. It's worth remembering this IS one web, but has many cultures and what fits one may not fit all.
I listened to Kevin Marks interview with Jemima Kiss at the Guardian and other than Kevin sounding incredibly similar to a friend of mind, the part that jumped out of me was his comments that many of the big social networks have done well out of users they just didn't expect. US technology companies growing "execpectedly" from string user bases in Russia, Brazil, China and so on - in other words from users NOT in North America.
So, I wrote on Twitter :
"that was an interesting interview Kevin. Given the cultural luck many networks
have do you think we need to put more work in involving other cultures right
from the start rather than once the technology is ready?"
Kevin Marks of Google made the point to me on Twitter that :
"the technology is ready, and has been for a while. Finding people to
bridge app ideas to other cultures and language is still hard."
My wording wasn't great (140 characters isn't much!) so this is what i meant....
Much of the technology driving the web is coming from specific locations in the US - mostly California - there is some input from the rest of us through discussion groups and so on, but primarily it is driven offline. This is understandable on many points due to the huge concentration of top people over there who are much like myself - driven and excited by the potential of the web as a platform that can fit into the daily life of everyone on the planet - in the many different ways people will use it. Also, at the moment virtual working groups are still a work in progress.
Now, oftentimes i get frustrated that i'm not amongst it - i had hoped to some years back startig with OpenID - (every week on twitter there is another cool event somewhere in the US where all the guys and gals get together to push these things forward). However, something that must be more frustrating is little involvement other cultures in the rest of the world must feel - at least i speak (bad) English and can follow in the forums and blog posts (and every so often post in the forums). What if you speak Chinese and want to use oAuth? Or Spanish? Say you want to add to it or suggest a change? There are a few involved, but this is very much the exception and if you check the board membership for most of these initiatives you can see they are based in the US and often (but not always) part U.S. web companies.
I think it is a problem waiting for a solution - the problem is how to integrate other languages and cultures so that the open web can be something that fits for everyone. If Orkut surprisingly managed to get a dominant user base in Brazil, was there something different to what other social networks were offering which made this happen? Does anyone know? In Africa it is suggested the uptake of mobile phones will continue to be huge - how do these efforts fit into their plans for a social web?
There are many of these folks who do a lot of evangelizing for these efforts so perhaps they can get to know active people who could get involved in the core specifications from Europe, Asia, Africa, South America and so on. It's worth remembering this IS one web, but has many cultures and what fits one may not fit all.
Thursday, October 9, 2008
Thoughts on Using Netflix’s New API
OK - I have read through Using Netflix’s New API: A step-by-step guide by Joseph Smarr and tried out a few of the things mentioned.
My only irritation in the excellent efforts Netflix have done are around the anomalies you can see in the API workflow.
i'm sure they have some good reasons for diverting from the "standard" process and perhaps some view to these may be useful.
In addition it may suggest some extension points are needed that could be added to oAuth so that rather than hacking these things we could simply add some optional extensions (which are generic such as "dynamic parameter" rather than "userid") and can be plugged into any oAuth library.
The fact this can even be done is excellent but in using it it would be nice to just have a graphical pipeline for every site that shows where they may have used some of the optional filters during the oAuth process.
Wednesday, October 8, 2008
Copy and Paste between OpenID's
In case you missed it i've added a new feature that allows you to Copy and Paste data between OpenID's.
More information can be found here.
More information can be found here.
Saturday, October 4, 2008
TESCO miss the point on the web and PR
Tonight we were expecting a home delivery from Tesco in Glasgow at 5pm. At 7.55 PM with the kids wandering where their milk was, we got a call saying they won't be coming due to "staffing issues". I am furious for obvious reasons - none worse than the fact i now need to go shopping to get breakfast for the kids for tomorrow and it is really late and pouring outside.
I am writing to them in response to an email i received so i will keep you updated and see how things progress (or don't).
--------------------------------------------------------------------------------------
Mr. Livingstone here. I included Terry Leahy in this and additionally will blog what happens at :
http://weblivz.blogspot.com/2008/10/tesco-miss-point-on-web-and-pr.html
Are you taking the piss? We have a 2 year old and a 5 year old who were waiting on milk before bed time because you were due to deliver before 7. You phone 1 HOUR late on a Saturday night to tell us this, asking if we can "come get it" !? You had from 5pm at the very,very latest to know of any apparent staffing issues.
What is WORSE is this pathetic general letter you have sent us - you never even took the time to send something personal. We never even had an opportunity to file any complaint and "you have been dissatisfied" is an understatement.
I would have been irritated at a cancellation earlier, but calling 1 hour later than the latest it was supposed to be here combined with a pathetic general letter (I assume the typists also had the evening off due to the rain) means we will no longer bother doing business with you and move to Asda or equivalent.
Additionally, I am a high profile online UK blogger and Internet consultant so you can bet a few people will hear about it and i will be looking out for someone at Tesco who can look into this.
Now I have got to go out into the pissing rain at 8 PM on a Saturday night to get milk for tonight and the kids breakfast for tomorrow morning.
For what it's worth - you don't need to concentrate on staff issues - you need to look at your PR... a phone call earlier in the day would have saved hassle for all of us.
steven
http://livz.org
________________________________
> From: online@tesco.co.uk
> Subject: Tesco Online Vouchers
> Date: Sat, 4 Oct 2008 19:51:19 +0100
>
>
> Dear Mr Livingstone
>
> Thank you for notifying us of your complaint. We value our customers' feedback, which helps us to monitor and improve our services.
>
> We are sorry to hear that you have been dissatisfied with the service you recently received from Tesco. As an apology we would like to offer you a ? 10.00 eCoupon, with our compliments, to spend on your next grocery order on Tesco.com. To use this eCoupon simply type in the code XXXXXXXXX when you reach Checkout. This eCoupon can be used from 4 Oct 2008 to 4 Jan 2009
>
>
> If you have any questions, you can also e-mail us at online@tesco.co.uk. Or you can contact our Customer Helpline on 0845 722 55 33 between 9am and 11pm Monday to Friday, 9am and 8pm Saturday and from 10am to 6pm on Sundays.
>
>
> Best wishes,
>
> -
>
> Tesco.com
>
>
>
> Tesco.Com Limited
> Company Number: 3942522
> Registered in England
> Registered Office: Tesco House, Delamare road, Cheshunt, Hertfordshire EN8 9SL
Thursday, October 2, 2008
Syndication in 2009
Had some thoughts on what could be done with Feed Aggregation sites such as http://weblivz.com/ and where it may all go. I decided to consider where we are, the problems we currently have and the inevitable move towards syndication for all.
This is a picture of where we stand today - a very much limited set of pre-defined feeds we can subscribe to (some such as twitter are doing some good work on improving this for their search).

So where are we going? Well, everyone needs to open up - and there are a whole load of good advantages to doing so. Personally, i think the fact we will be able to write complex queries is a major advantage - users are just never going to learn anything more than AND/OR - but we can improve their results by employing the advanced capabilities of search engine logic and API's.
Additionally we want to start using the Semantic Web, but how a user would work with Google Base or FreeBase etc isn't entirely straightforward. It really comes down to either providing an interface they can build upon or writing the queries for them - perhaps in a templated more to substitute their specific query (ala OpenSearch).
Whatever method is used people want RSS/Atom. Feeds just now are starting to get out of control because even a reliable source have a small percentage of data you really want. We now need to be able to write custom queries to request exactly what we want. To join, filter, deduplicate and so on.
I fully expect in the next year or so that the advances that have already started in these areas will only gain momentum and make it a hell of a lot easier for us to get results.
Will be see a "RSS" button on each page of the Google Search results by the end of 2009?

Subscribe to:
Posts (Atom)